Overview
Architecture & System Design
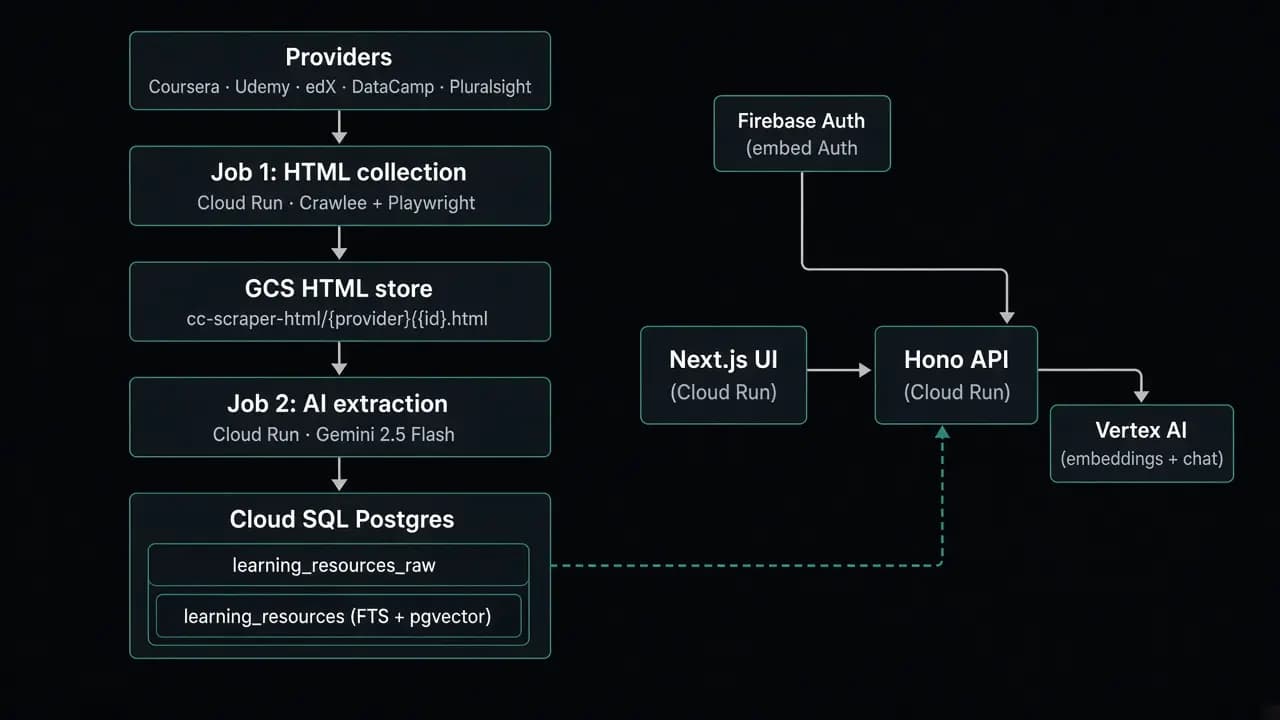
- Client: Next.js App Router UI (MUI). Owns search UX, detail pages, subjects, saved list, and the Cora chat panel. Talks to the 1.5 REST/SSE API.
- Server / API: Hono on Node. Hybrid search, resource detail, Firebase→JWT exchange, chat streaming with RAG context, usage limits. Shared Drizzle schema with the scraper so types are not duplicated.
- Data: Two layers: raw extraction JSON keyed to GCS HTML, and normalized learning_resources that power every user-facing query. Soft-delete via is_active so incomplete crawls never wipe the catalogue. Search uses a weighted tsvector trigger plus 768-d Vertex embeddings (HNSW).
- Background jobs: Cloud Scheduler triggers per-provider Cloud Run Jobs. Job 1 only fetches and stores HTML (rate-limited, retries). Job 2 is provider-agnostic extraction + upsert. Failed or dry runs skip stale-marking so a partial crawl cannot deactivate the world.
- Integrations: Firebase Auth (unchanged from v1), Vertex AI (embeddings + Gemini), Impact affiliate URL templates, O*NET-grounded career insight generation (pipeline; on-demand UI still evolving).
Tech Stack & Rationale
- Architectural Pragmatism & Cost Discipline: Built production-grade hybrid vector search and LLM extraction on GCP serverless primitives and Cloud SQL, deliberately skipping dedicated search SaaS platforms and headless CMS abstractions to keep monthly infrastructure run costs near zero without sacrificing data quality or retrieval performance.
Engineering Trade-offs
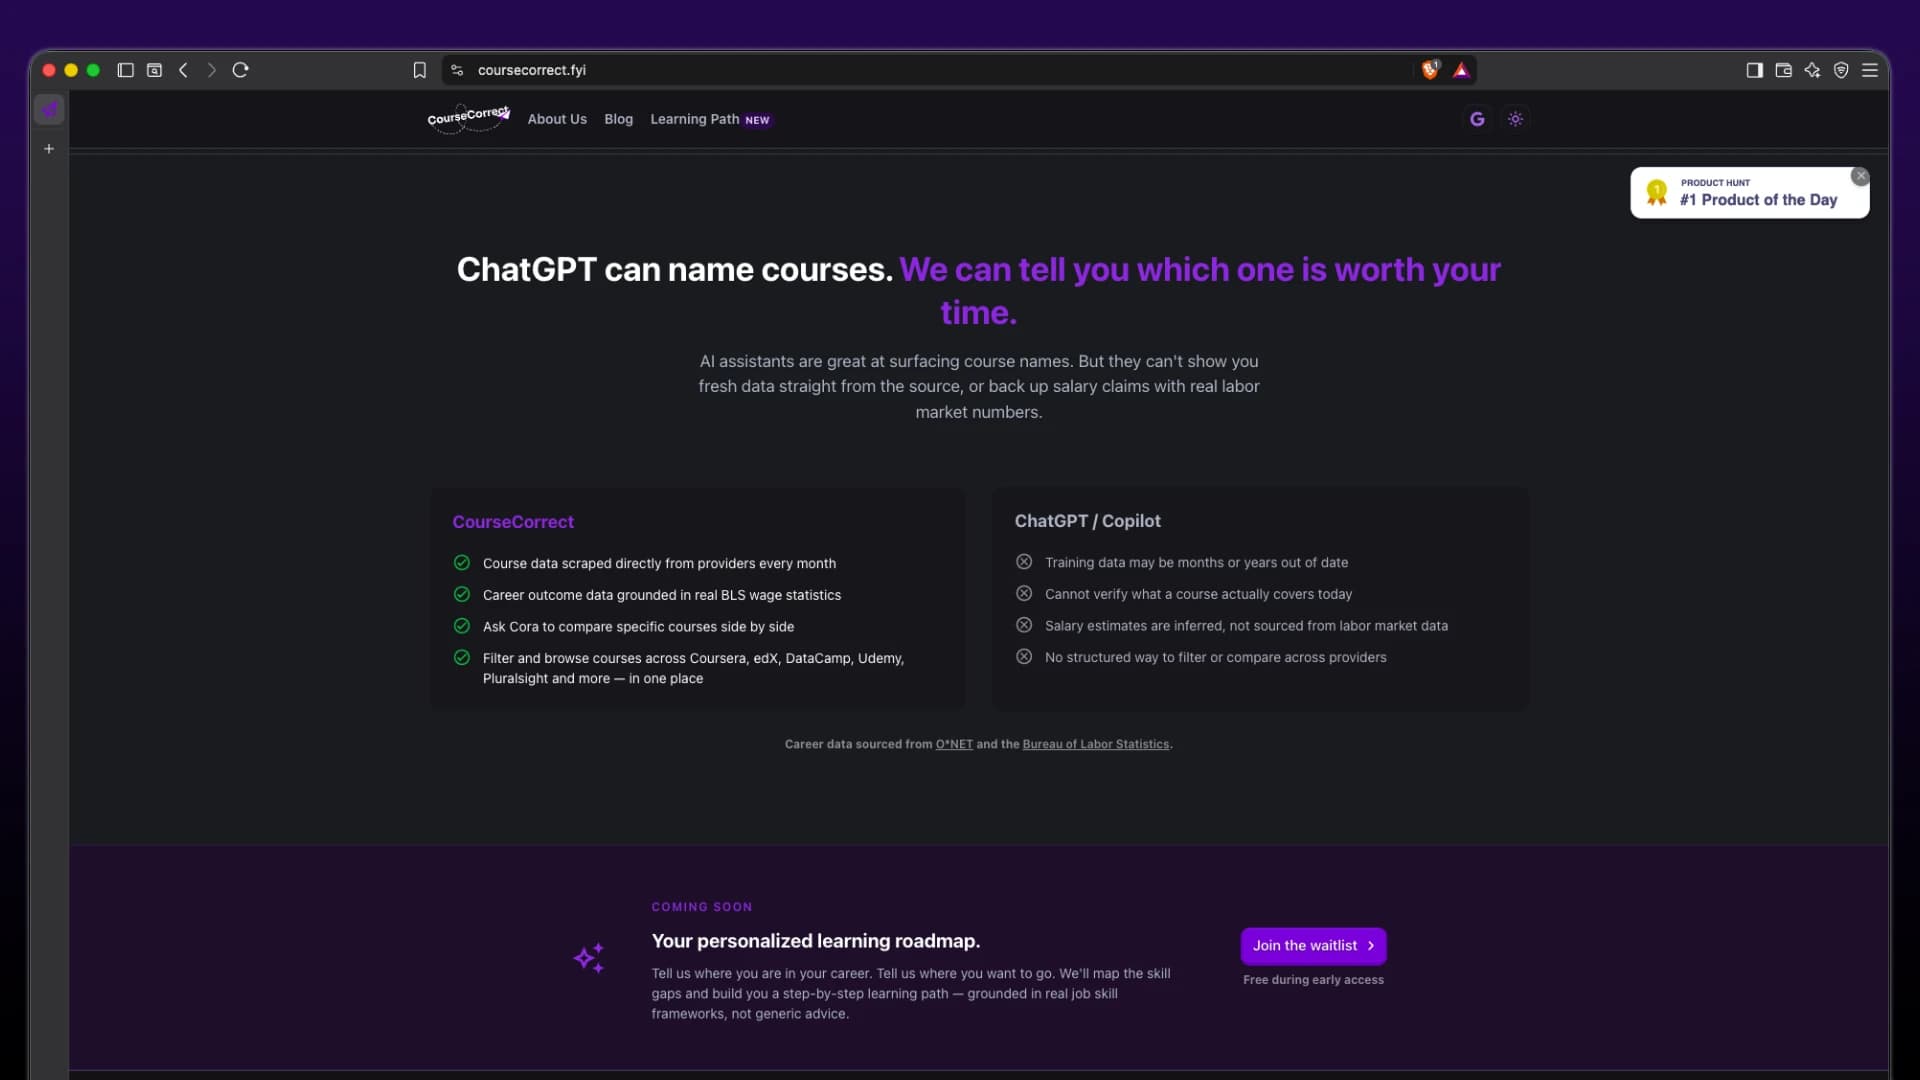
- Editorial layer over aggregator mirror. Storing provider marketing copy verbatim is the easy path and the undifferentiated one. AI summaries, normalized skills/levels/durations, and a user-meaningful type taxonomy cost extraction spend and prompt iteration, but they are the product moat versus Class Central-style mirrors and versus chatbots that invent stale lists.
- Two-job scrape vs scrape-and-parse in one pass. Decoupling HTML collection from Gemini extraction means prompt improvements re-run on GCS without touching providers again (“no selector maintenance” as a design goal for the editorial fields). The cost is operational complexity (two job types, run status, stale marking rules) and temporary raw rows without extracted_data.
- Postgres consolidation vs specialized stores. Moving off MongoDB Atlas (~CAD $70/mo alone in the prior setup) plus Qdrant into one Cloud SQL instance simplified ops and cut vendor sprawl. The trade-off is owning FTS + vector tuning yourself (weights, HNSW, embedding backfills) and accepting that a mis-sized instance shows up as a single bill line, worth watching as the catalogue grows.
- Hybrid ranking weights chosen for relevance, not fashion. Implemented score blends keyword and semantic signals with a keyword-only fallback when embeddings are missing. Docs and code drifted on exact coefficients during iteration; the principle that mattered was: never fail closed to empty results when vectors are cold, and never rank only on marketing popularity.
- Soft-delete + conservative stale marking. Auto hard-delete is tempting for “freshness.” We soft-deactivate only after completed/partial runs, never after failed or dry-run subsets. That protects SEO URLs and saved items at the cost of occasional zombie rows until a clean full run.
- What we deferred. LinkedIn/profile-based roadmaps, subscriptions, deep hierarchy navigation (specialization → child courses), and perfect provider coverage (Skillshare and others still opportunistic). Also known data-quality debt on some duration_hours for long programs. That is fixable, but not something to hide in a portfolio write-up.
Key Features
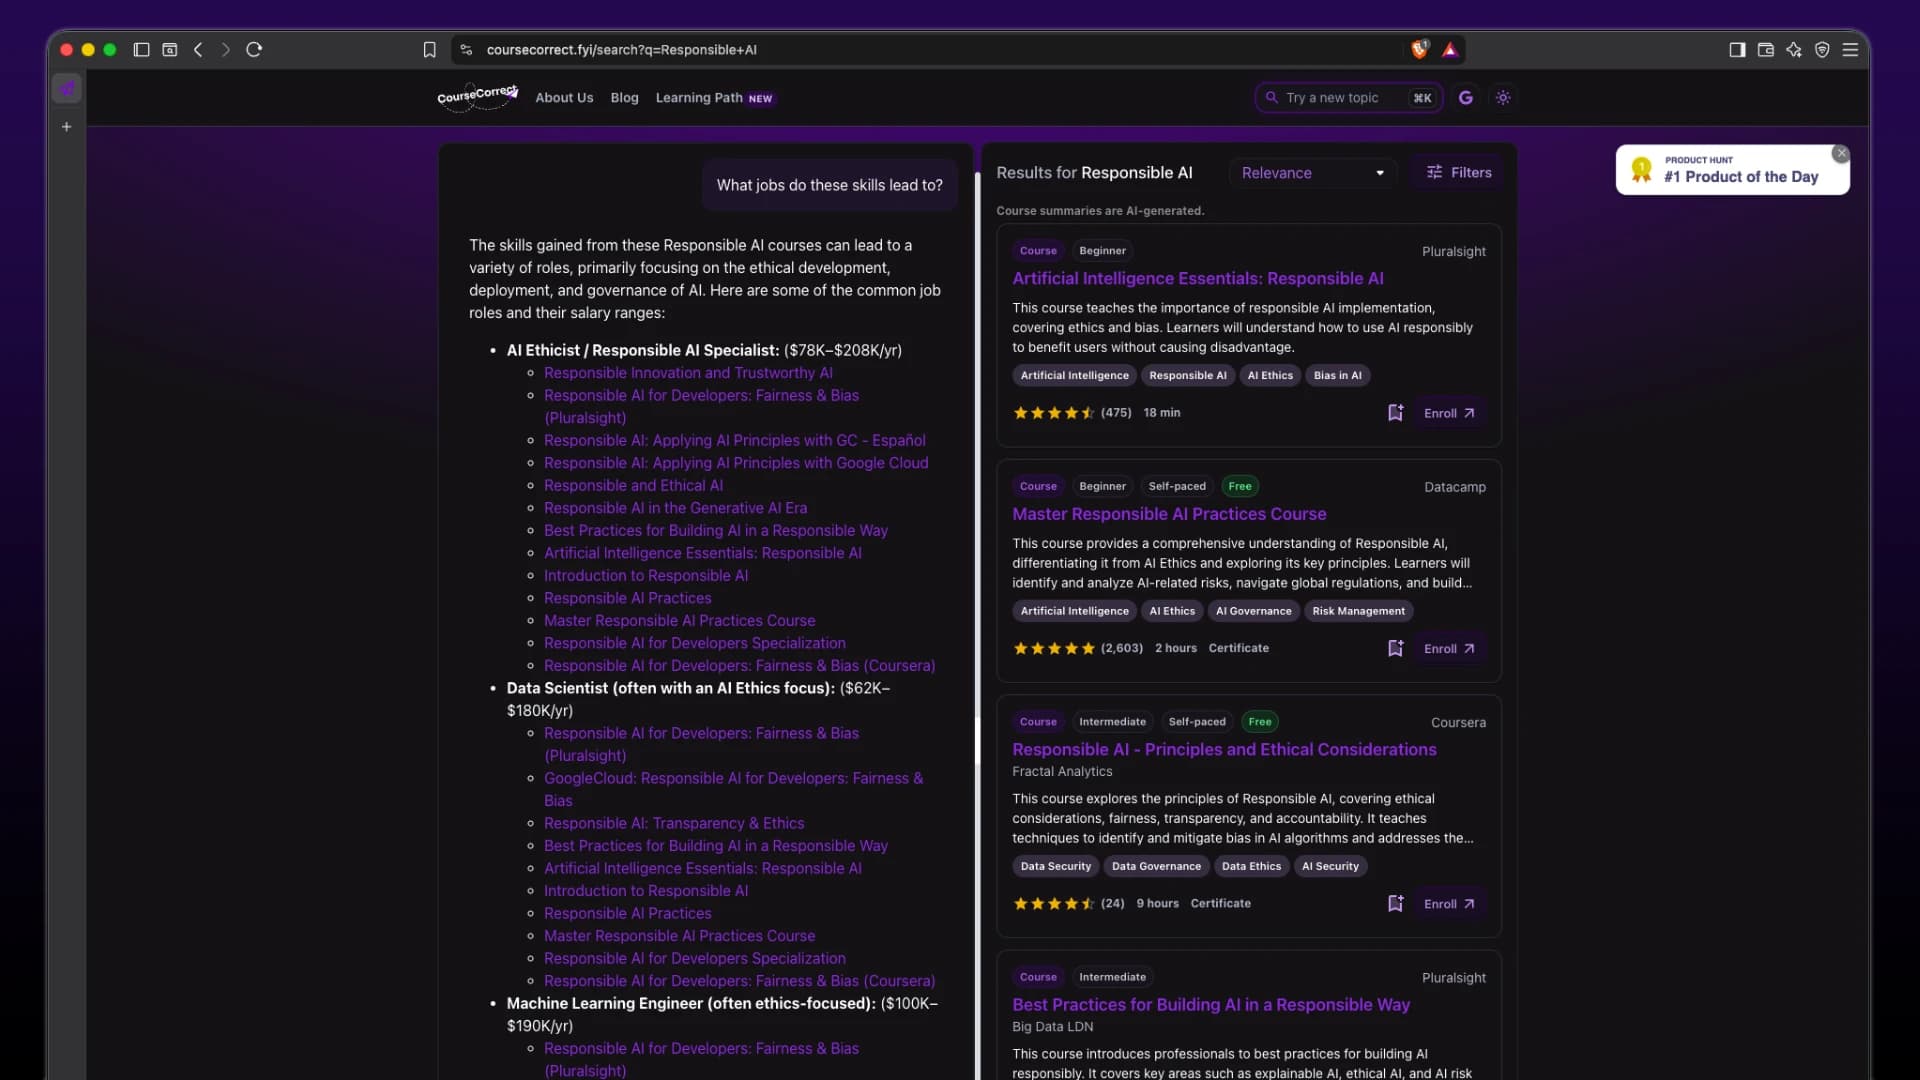
- Hybrid catalogue search: Keyword + semantic ranking with filters (provider, type, level, language, free, certificate) and sorts (relevance, rating, reviews, duration, newest). Cursor pagination avoids offset drift.
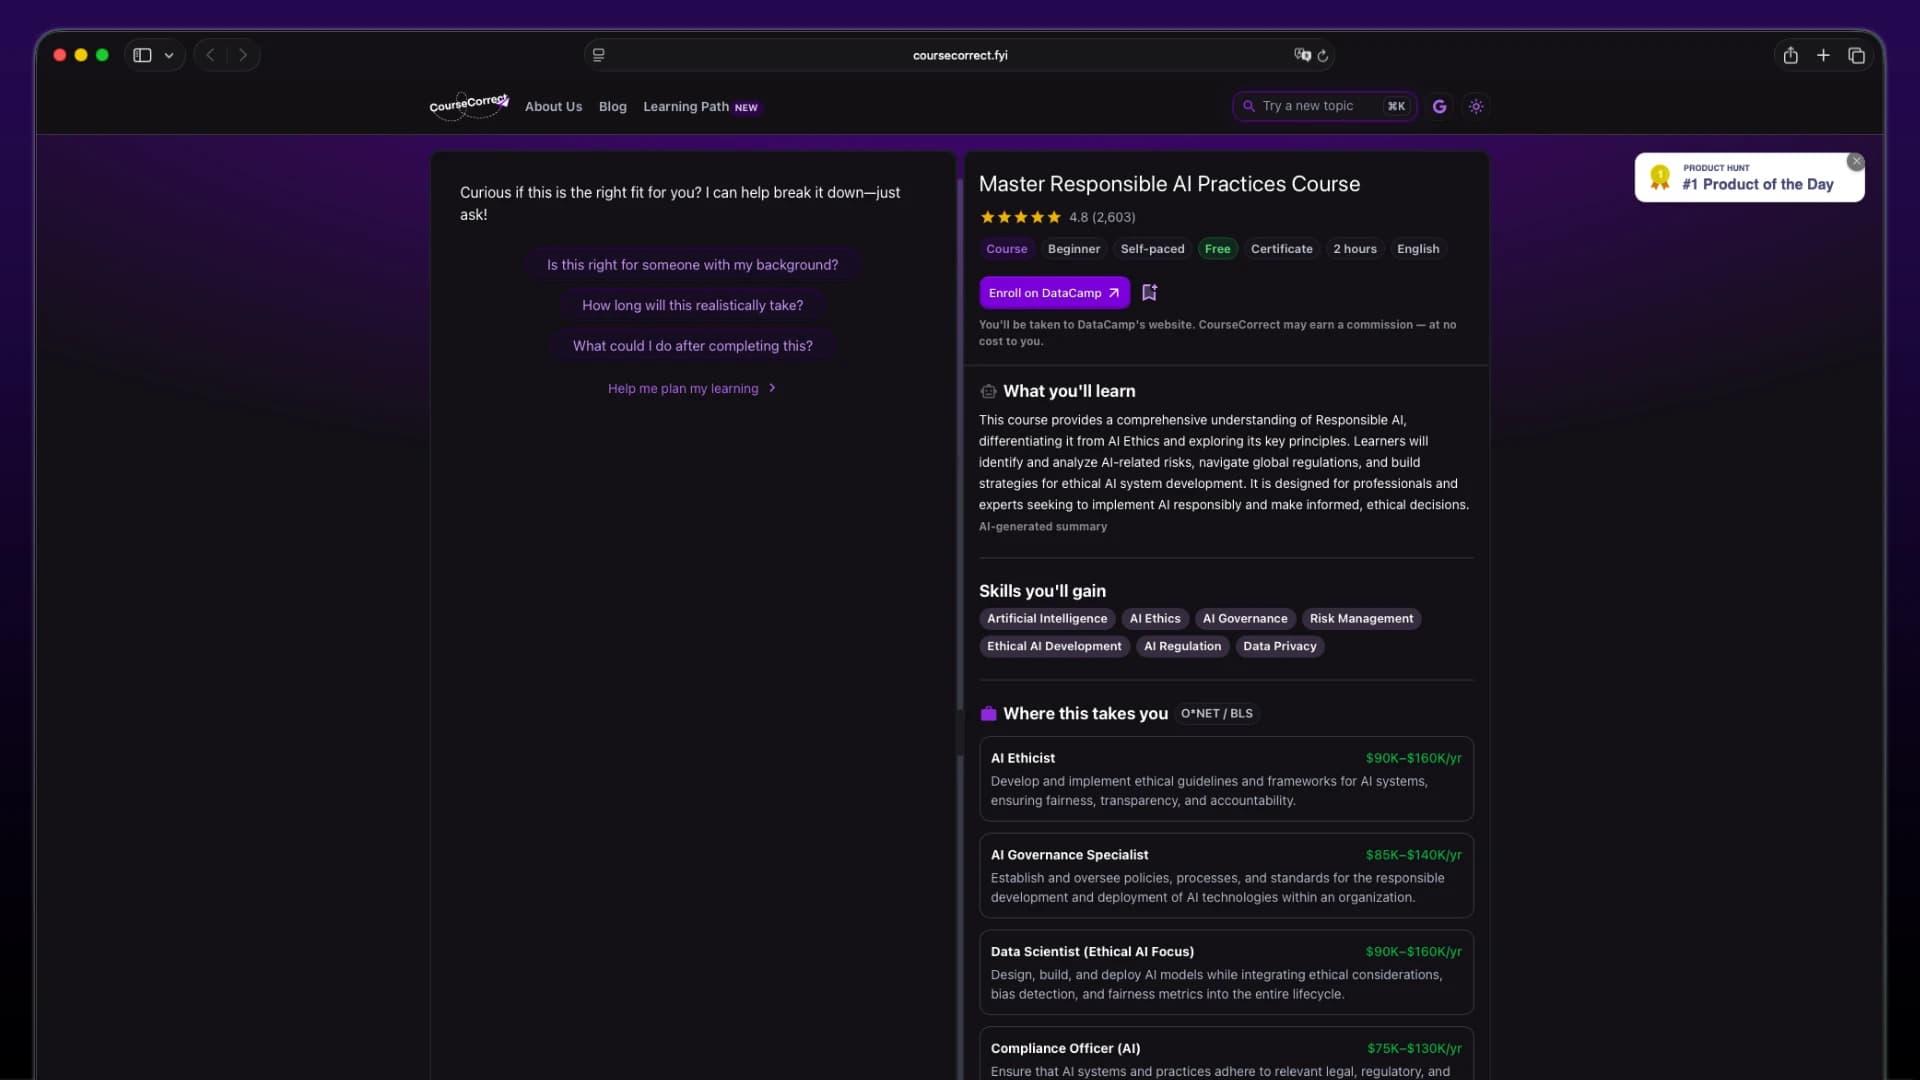
- AI-normalized detail pages: Plain-English summaries and skills aimed at decision-making, not brochure copy; enroll CTA prefers Impact affiliate_url, falls back to canonical source_url.
- Cora (RAG chat): SSE streaming assistant with catalogue retrieval beyond the on-screen set; daily query caps for signed-in and anonymous users so Vertex spend stays bounded.
- Subjects / topics: SEO topic pages backed by the topic catalogue and hybrid search (join-table density still intentionally incomplete).
- Saved courses + auth: Firebase identities, backend JWT, bookmarks that survive the 1.5 data migration path (including legacy URL / legacy_mongo_id compatibility work).
- Ingestion observability: Per-URL run results (outcome, error type, GCS snapshot key) so scrape failures are diagnosable instead of silent catalogue rot.
Outcome
- Owned the 1.5 rebuild end to end: provider scrape → GCS → Gemini extract → Postgres (FTS + pgvector) → hybrid search and catalogue RAG.
- Replaced a Class Central-dependent / multi-store data path with direct provider collection and a single Postgres system for relational data, full-text search, and vectors.
- Built a re-runnable editorial pipeline (GCS HTML → Gemini → normalized catalogue) designed for monthly refresh and prompt iteration.
- Shipped hybrid search and catalogue-RAG chat on that foundation, with auth and saved courses preserved across the rebuild.
- Kept GCP shape intentionally boring: Cloud Run services/jobs, Scheduler, Secret Manager, Firebase, operable by a small team.
- Finish any remaining legacy → 1.5 cutover and dual-deploy cleanup.
- Fix duration normalization for long programs before leaning on duration sort.
- Deepen topic-to-resource linking for subject pages.
- Migrate Postgres from always-on Cloud SQL to Neon (scale-to-zero). Measured API traffic is mostly idle, so paying for a full Cloud SQL instance is the main leftover cost; Neon Launch is the planned fit without rewriting the app (TCP DATABASE_URL cutover).
- Only then invest in 2.0 personalization (profiles, LinkedIn, roadmaps) on top of a trustworthy catalogue.